Local LLMs: deployment and operation in corporate infrastructure (AILOC)
AI - Artificial Intelligence, AI for developers
Local language models enable generative AI without sending corporate data to the cloud, while providing full control over infrastructure, costs and security. This course is ideal for system administrators, DevOps specialists and IT architects who need to design, deploy and operate local AI in their organisation.
You will learn how to correctly size hardware, choose the right open-weight model and quantization, and deploy it using Ollama, llama.cpp and vLLM, from a workstation to a multi-GPU server. We will cover GPU resource management in GPUStack, an internal chatbot with RAG over corporate documents in Open WebUI, integration with development tools and coding assistants, and securing the entire solution for production operation. The course is highly practical and led by instructors with real-world experience operating local models.
THIS TRAINING COURSE WILL HELP YOU:
- Understand how inference works and what determines a model's VRAM, RAM and performance requirements
- Design and size hardware for local AI, including GPUs, multi-GPU systems and unified memory platforms
- Choose the right model based on the task, language, licence and available hardware
- Deploy models with Ollama, llama.cpp and vLLM in Docker and Kubernetes
- Expose models through OpenAI-compatible APIs, Open WebUI and development tools
- Implement authentication, data protection, monitoring and resilience against prompt injection
WHO SHOULD ATTEND?
- System administrators responsible for deploying and operating local models
- DevOps and platform engineers building inference infrastructure and internal AI APIs
- IT and solution architects deciding between local, on-premise and cloud solutions
COURSE LOCATION AND AVAILABLE DATES
Filter dates:
DateLocationFormat
LanguagePrice
PrahaPraha (hybrid)
Hybrid
This session takes place simultaneously in the classroom and online. You can choose your preferred way to attend during registration.
Czech
472 € 571 € incl. VAT
Need this course in English?
Public courses are usually delivered in Czech, but this course is also available in English. We can arrange private training for your team online, at your premises or in our classrooms, and tailor the content to your needs.
For groups of around 4 or more participants, private training can already be comparable in price to booking individual places on a public course. Send us your requirements and we’ll recommend the best format and provide an exact quote.
Request training in English
Course content:
Hide details
-
Local model fundamentals
-
What is a local LLM and how inference works
-
Local model versus cloud API and on-premise service
-
Open source, open-weight and proprietary models
-
Model parameters, layers, tokens and context window
-
VRAM, RAM, CPU, GPU and storage requirements
-
Quantization: FP16, BF16, INT8, INT4 and GGUF
-
Impact of model size on quality and performance
-
Chat, base, reasoning, coding and multimodal models
-
Embedding and reranking models
-
Inference, RAG, fine-tuning, LoRA and QLoRA
-
Model selection by task, language, licence and hardware
-
Benchmarks, evaluation and practical testing
-
Limitations of local models and common errors
-
Security and data protection
-
Hardware and operating environment
-
Workstation versus corporate server
-
NVIDIA, AMD, Intel and CUDA
-
VRAM, multiple GPUs, CPU and hybrid inference
-
Linux, Windows, WSL, Docker and Kubernetes
-
Performance, power consumption, cooling and monitoring
-
Infrastructure benchmarking and sizing
-
Unified Memory platforms, Strix Halo platform, Mac Studio, RTX Spark, DGX Spark and more
-
Ollama
-
Rapid model deployment on a workstation
-
Model management and basic configuration
-
API for connecting applications
-
llama.cpp
-
GGUF and quantized models
-
CPU, GPU and various backends
-
llama-cli and llama-server
-
Offloading layers to the GPU
-
Configuring context and inference parameters
-
OpenAI-compatible API
-
Operation on workstations and servers
-
Basic optimization and benchmarking
-
vLLM
-
vLLM architecture
-
OpenAI-compatible API
-
PagedAttention and continuous batching
-
High throughput for multiple users
-
Tensor parallelism and multiple GPUs
-
Prefix caching and speculative decoding
-
Quantized and multimodal models
-
LoRA adapters
-
Deployment in Docker and Kubernetes
-
Monitoring and production operation
-
GPUStack
-
Managing GPU workers and models
-
Deployment across multiple servers and GPUs
-
Resource allocation, monitoring and scaling
-
Integration with inference engines
-
Open WebUI
-
Connecting Ollama, llama.cpp and vLLM
-
Managing users and models
-
Knowledge base and RAG
-
Tool integration and internal chatbot
-
Open source models
-
Qwen, Gemma, Llama, Mistral, DeepSeek, GPT-OSS and more
-
Coding, reasoning and multimodal models
-
Current developments in open source models
-
Licensing and commercial use
-
Benchmarks and practical model selection
-
Quantization, LoRA and fine-tuning
-
Integration with development and other tools
-
VS Code
-
Aider
-
IntelliJ IDEA
-
Open Code
-
OpenClaw
-
Continue, Cline, Roo Code and more
-
Local coding assistant
-
Agent workflows and tool integration
-
Corporate operation and security
-
Internal APIs and model sharing
-
Authentication and SSO
-
Protection of sensitive data
-
Prompt injection and agent security
-
Monitoring, backups and updates
-
RAG over corporate documents
-
Hybrid local and cloud architecture
-
Schedule:
-
2 days (9:00-17:00)
-
Price per person:
-
472.00 € ( 571.12 € incl. 21% VAT)
Training and learning environment
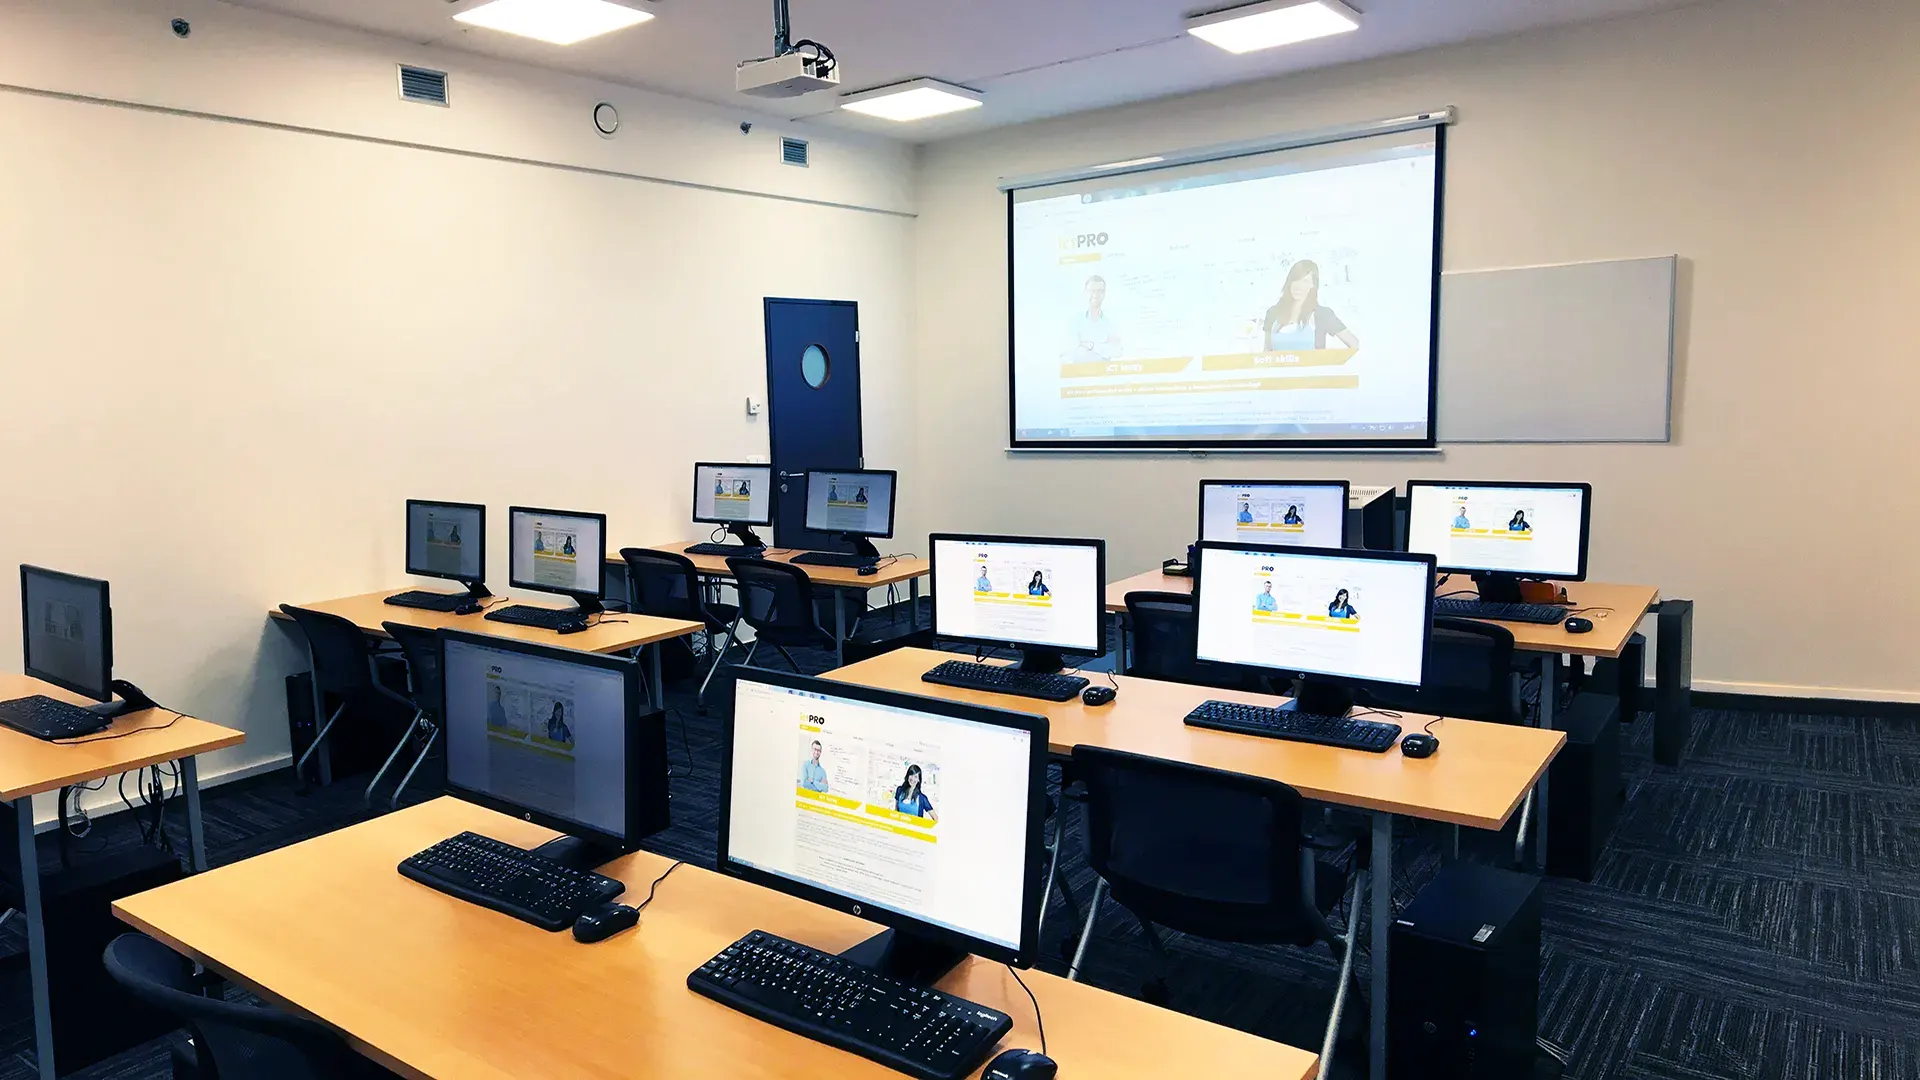 What does the environment for in-person IT courses look like?We hold training courses in our own classrooms equipped with modern computer equipment for each participant and a large projection screen. Each workstation is fitted with a powerful computer for seamless practical exercises, and the environment supports a calm, friendly atmosphere during training.
 Do I need to bring my own laptop to the classroom IT course?Our training rooms are fully equipped, so you do not need to bring your own laptop. A modern computer with all necessary hardware and software is ready for you at your workstation.
 Will you receive an official certificate after completing an IT course?Yes, upon successful completion of the training course, you will receive an official ICT Pro certificate confirming your participation and acquired technical skills. You can use it to verify your qualifications or add it to your professional profile.
 Where can you find our training center in Brno?The premises of the ICT Pro training center are located on the 1st floor of the COMGUARD building at Sochorova 38 in Brno. Positioned on the border of Žabovřesky and Komín, the location is easily accessible by both car and public transport.
 Where can you find our training center in Prague?The premises of the ICT Pro training center are located on the 1st floor of the Opatov Park building at Líbalova 1, Prague 11 – Chodov. The location provides a comfortable environment for your education with convenient access.
 What facilities and refreshments are available to you during training breaks?Our training centers feature a fully equipped kitchenette for a comfortable break during your courses. The facilities include a coffee machine, microwave, kettle, and a wide selection of drinks and snacks.
 What beverage refreshments are available during your course?A beverage station with a coffee machine, teas, syrups, and water is at your disposal throughout the entire training session. You can enjoy a coffee or another drink of your choice anytime during breaks.
 What light refreshments are provided for you during the courses?During course breaks, participants can enjoy light sweet snacks, pastries, and fruit syrups to mix their own drinks. Fresh water dispenser and plates are also available for your convenience.
 Should I bring my own snacks to ICT Pro training?There is no need to. A wide selection of savory snacks, sweet biscuits, and snack bars is available for you during breaks. Boost your energy for all-day focus right inside the training center premises.
 Can you spend training breaks in the fresh air?Yes, an outdoor terrace is available at our training center. During breaks between learning sessions, you can relax in the fresh air in a pleasant green environment.
 Where can you relax during course breaks?Our training center features a spacious outdoor terrace with seating options. During breaks between learning sessions, you can step outside to relax and recharge in the fresh air.